Laritor
Yes
Laritor vs Queuewatch
Laritor tracks exceptions, detects issues, and monitors Laravel performance. Investigate failed jobs with their related queries, API calls, and logs. Monitor requests, queues, and user journeys in the same place, then debug with in-app AI or your coding agent through MCP.
Published by Laritor · Comparison checked · View comparison notes
Designed primarily for Laravel. All tools compared here support Laravel.
Yes
Yes
Why choose Laritor over Queuewatch?
Queuewatch helps teams manage queue failures and workers. Laritor helps you find why a job failed, what made a request slow, and how a problem affected a user. Choose Laritor when you want queue monitoring and broader Laravel application visibility together.
The full feature comparison
Compare 38 capabilities. See where Laritor gives you more, where Queuewatch has an advantage, and what both tools offer.
“Not listed” means a dedicated feature was not found in the public documentation reviewed. Queuewatch already provides useful failure reports, alerts, remote retries, and released worker monitoring. Those are compared separately from Laritor’s related execution timelines and application-wide monitoring. The released v1.3.1 client is used where older documentation differs.
Related execution events, application-wide exceptions, request performance, dashboards, session journeys, in-app AI, and MCP.
| Capability | Laritor | Queuewatch |
|---|---|---|
| Exception tracking across your Laravel app | Beyond failed jobs Exceptions from retained requests, jobs, commands, and scheduled executions. | The Laravel package automatically reports JobFailed events. Automatic application-wide exception collection is not listed. |
| Events leading up to a failed job | Find the root cause Inspect the retained job’s queries, API calls, logs, cache events, and other recorded activity. | Failure report with exception details, job payload, attempts, queue, and server metadata. A correlated execution timeline is not collected by the reviewed listener. |
| Per-job dispatch, wait, and execution timing | Find queue bottlenecks Compare dispatch delay, worker wait, execution duration, and throughput alongside retained job events. | Worker lifecycle, processed counts, memory, and advertised queue analytics. Per-job dispatch/wait/execution timing with related event timelines is not listed in the reviewed integration. |
| HTTP request performance | Monitor request performance Request timings, duration percentiles, status codes, failures, and retained request details. | Queue-focused monitoring. An HTTP request performance resource is not listed. |
| SQL queries and bindings | Find slow queries Inspect query timing, SQL, bindings, and related recorded executions. | No automatic query listener or correlated query collection in the reviewed failure integration. |
| Outbound API investigation | Understand failing API calls Optional outbound headers, payloads, responses, duration, and related errors. | Reports the failed job’s exception and payload. An outgoing HTTP request collection resource is not listed. |
| Artisan commands and output | Investigate failed commands Command executions, failures, captured output, and recorded events. | Enhances queue:failed for inspecting local failures. General command execution and output monitoring are not listed. |
| Scheduled task investigation | Monitor scheduled work Scheduler execution details, failures, delays, and related recorded activity. | Uses the scheduler to flush worker heartbeats. General scheduled task monitoring is not listed. |
| Cache behavior | Understand cache usage Inspect cache events and hit/miss metrics across retained activity. | Uses a shared cache for worker heartbeats. Application cache analytics are not listed. |
| Application logs | Read the logs behind a failure Search recorded logs and inspect them inside retained execution timelines. | Exception messages and failure context. Automatic application log collection is not listed. |
| Mail and notification activity | Inspect delivery activity Dedicated mail and notification resources linked to recorded executions. | Can report a failed email or notification job. Separate mail and notification activity resources are not listed. |
| Laravel session journeys | Follow the customer’s journey Follow recorded requests across a user’s session, including custom milestones. | Projects, environments, jobs, and failures. A cross-request session journey is not listed. |
| Automatic Pennant insights | Understand feature rollouts Feature flag evaluations, activation rates, durations, and related errors. | Automatic Laravel Pennant performance monitoring is not listed. |
| Host CPU, memory, and disk | Code and server resources Optional host resource collection and dedicated CPU, memory, and disk charts. | Worker heartbeats include process memory. Dedicated host CPU and disk resource monitoring is not listed. |
| Custom dependency health checks | Check your dependencies Run checks inside Laravel and inspect result history and failures. | Queue failure and worker monitoring. A general dependency health check resource is not listed. |
| Database schema explorer | Schema-aware debugging Browse tables, columns, indexes, and relationships beside recorded queries. | A database schema explorer is not listed. |
| Business milestones and custom events | Understand business workflows Named custom events with metadata and timing, execution timelines, resources, and dashboards. | Failure reports and a REST integration. A dedicated business event resource and dashboard system are not listed. |
| Unlimited customizable dashboards | 85+ widgets Build unlimited dashboards with 85+ Laravel widgets. | Queue failure dashboards and analytics. An equivalent customizable widget dashboard builder is not listed. |
| Custom daily and weekly PDF reports | Share application snapshots Choose performance metrics and receive scheduled PDF snapshots by email. | Failure analytics. Custom scheduled PDF application performance reports are not listed. |
| Bot and suspicious request views | Understand automated traffic Dedicated traffic analytics, detection settings, and recording filters. | Bot and suspicious HTTP traffic monitoring is not listed. |
| Exception, issue, and full recording modes | Record what you care about Retain configured activity only for exceptions, detected issues, or every execution. | Failure reporting with ignore lists, plus optional worker monitoring. Application-wide recording modes are not listed. |
| In-app AI and MCP debugging context | Debug with your AI agent In-app recommendations, configurable AI providers, and read-only exception context through MCP. | Failure reports, retries, and REST integration. An in-app AI assistant or MCP server is not listed in the reviewed documentation. |
| Unlimited apps and users on the starting paid plan | Room for your team Unlimited apps and users at $20/month. | Pro includes five projects and one member. Team includes 20 projects and unlimited members; Business removes the project limit. |
Remote retries, worker lifecycle monitoring, failure resolution workflows, an enhanced CLI, report-based pricing, and longer history on higher tiers.
| Capability | Laritor | Queuewatch |
|---|---|---|
| Remote failed-job retry | Investigate a failed job and use Laravel’s retry workflow. A dashboard-triggered remote retry endpoint is not documented. | Retry from the dashboard after enabling the signed callback and configuring its URL. The released client uses the project API key for HMAC verification. |
| Worker lifecycle and heartbeat monitoring | Queue execution, dispatch delay, wait time, and throughput investigation. | Opt-in worker starts, heartbeats, process memory, and stops on Laravel 12.20+. Stop reason availability depends on the Laravel version. |
| Failed-job resolution audit workflow | Exception and issue investigation with status management. | Queue-specific acknowledgment, resolution notes, and an audit trail of who resolved a failure. |
| Failure resolution analytics and health score | Job and issue metrics, performance views, and custom dashboards. | Failure trends, resolution rate, average resolution time, and a queue health score based on failure management. |
| Enhanced local failed-job CLI | Web resources and MCP for recorded monitoring data. | Extends queue:failed with JSON output and queue, connection, date, and class filters. Local CLI use does not require a hosted account. |
| Longer included history on higher tiers | 30-day retention on the standard paid plan. | 30 days on Pro, 90 days on Team, and one year on Business. |
| Failure-report billing | Counts retained executions and related events, including 2 KB size increments. | Published paid allowances count failed-job reports. No separate query or log event fee is listed for those reports; their contents are narrower than a Laritor timeline. |
Both provide hosted Laravel failure monitoring, job and exception context, notifications, filters, project labels, and team access.
| Capability | Laritor | Queuewatch |
|---|---|---|
| Failed-job exception details | Exception class, message, file, line, full stack trace, and occurrence context. | Exception class, message, file, line, and trace. The released listener caps the transmitted trace at 20 frames. |
| Job payload and attempt context | Job payload, queue, connection, attempts, failures, and related retained events. | Job payload, queue, connection, attempts, max tries, timeout, and environment metadata. |
| Failure alerts | Configured alert integrations, including email, Slack, Discord, and webhooks. | Email, Slack, Discord, and webhook notifications, with channel availability depending on the plan. |
| Client-side filtering | Collection controls, recording filters, and sampling before ingestion. | Ignore specific jobs, queues, or exception classes; job payload collection can be disabled. |
| Laravel Composer integration | Install the Laravel client and configure your ingest endpoint and key. | Install queuewatch/laravel and configure a project API key. Worker reporting and remote retry require additional opt-in setup. |
| Hosted monitoring storage | Managed ingestion, storage, and monitoring interface. | Hosted failure dashboard, notifications, and report storage. No monitoring database is required in your own app. |
| Team access | Shared apps and dashboards with unlimited users on the paid plan. | Project collaboration and roles, with unlimited members on Team and Business. |
| Project and environment context | Recorded activity grouped by application and environment. | Failure reports include project and environment labels for filtering and notifications. |
Major difference
Laritor gives you the recorded activity inside a job, not just a failure report. Understand queue performance and connect job problems with the requests, queries, and API calls around them.
Read the recorded queries, outgoing API calls, cache activity, logs, and exception context. Queuewatch’s failure reporting integration does not capture this complete related-application-event timeline.
Laritor shows queue wait, execution duration, and throughput. Queuewatch adds failure analytics and worker lifecycle monitoring, but comparable per-job wait and correlated execution views are not listed.
Use Laritor for requests, commands, scheduled tasks, queries, sessions, dashboards, and reports. Queuewatch’s focused queue workflow leaves those wider application investigations to other tools.
Why choose Laritor over Queuewatch?
Start with the failed job. Follow the recorded events that explain it, then use the same tool to improve requests, queries, and the wider application.
20M billable events, unlimited apps and users, and 30-day retention. Choose exceptions, detected issues, or all activity without a separate error or log quota.
Both tools publish USD prices, with different billing units and terms. Laritor uses monthly event billing; the calculator labels Queuewatch’s published annual monthly equivalents and compares the same failed-job workload.
Cost calculator
Use one failed-job volume for both tools. Queuewatch counts failure reports. Laritor counts the recorded failure and its related billable events.
100,000 billable events · 30-day retention
10,000 failed-job reports included · 90-day retention
Selects a paid Queuewatch tier by report volume. More projects or team members may require a higher tier. Queuewatch prices are published annual monthly equivalents, requiring annual billing. Laritor uses monthly billing. The free tier is excluded.
USD before tax. Queuewatch publishes annual monthly equivalents of Pro $16/1,000 reports, Team $48/10,000 reports, and Business $160/unlimited reports. The public page mixes annual and reference prices, so no monthly subscription rate is inferred here. Confirm current checkout pricing, worker entitlement, and API limits with Queuewatch. Laritor includes 20M billable events for $20/month, adds $0.20 per started 100K above that, and shows “Ask for a quote” above $500/month. This estimate covers failed jobs only. Other retained application activity adds Laritor events. Trials, free allowances, tax, custom contracts, and optional enterprise hosting are excluded.
A failure message tells you what broke. Related events help explain why.
Queue performance
Compare dispatch delay, worker wait, execution duration, and throughput. Open a retained job to see whether queries, API calls, or another operation made it slow.
Queuewatch includes worker lifecycle monitoring and advertises queue analytics. Laritor adds per-job timing investigation with the recorded events inside each retained execution.
Execution context
Open a retained job and inspect its queries, API calls, logs, cache activity, and custom events. Find the failed dependency or unexpected value before changing the code.
Queuewatch records useful job and exception details. Its released failure listener does not collect a correlated timeline of the operations inside that job.
Outbound requests
Inspect configured outgoing headers, request payloads, response content, status codes, and timing. Connect an external API failure to the job or request that made the call.
Queuewatch can report the resulting failed job and exception. Laritor also records the HTTP call itself so you can investigate the response that caused the problem.
Server resources
Compare application timings with host CPU, memory, and disk charts from optional scheduled collection. Investigate database work and capacity in the same monitoring tool.
Queuewatch’s worker heartbeats include process memory, so it already provides useful worker context. Laritor adds dedicated host resource monitoring beyond a worker process.
Use the same investigation workflow across your Laravel app.
Application exceptions
Investigate exceptions from retained requests, jobs, commands, and scheduled tasks. Inspect the file, line, full stack trace, and the activity that led to the exception.
Queuewatch’s Laravel integration reports JobFailed events. It is useful for permanently failed jobs; it does not automatically collect every exception elsewhere in the application.
Commands and scheduled tasks
Inspect command output, errors, queries, and related recorded activity. Use dedicated scheduler views to investigate scheduled executions and delays.
Queuewatch enhances the local queue:failed command and uses a scheduled heartbeat flush. Those features serve queue operations; general command and scheduler monitoring are not listed.
Debug with your AI agent
Laritor MCP lets your agent retrieve exception details and the recorded execution timeline. It can inspect those events alongside your code to investigate the cause and work on a fix. In-app AI recommendations are available too.
Laritor lets you choose your in-app AI provider. Queuewatch documents REST integration and remote retries; an equivalent in-app AI assistant or MCP server is not listed in the reviewed documentation. Choose your in-app AI provider ↗
Read the Laritor MCP guide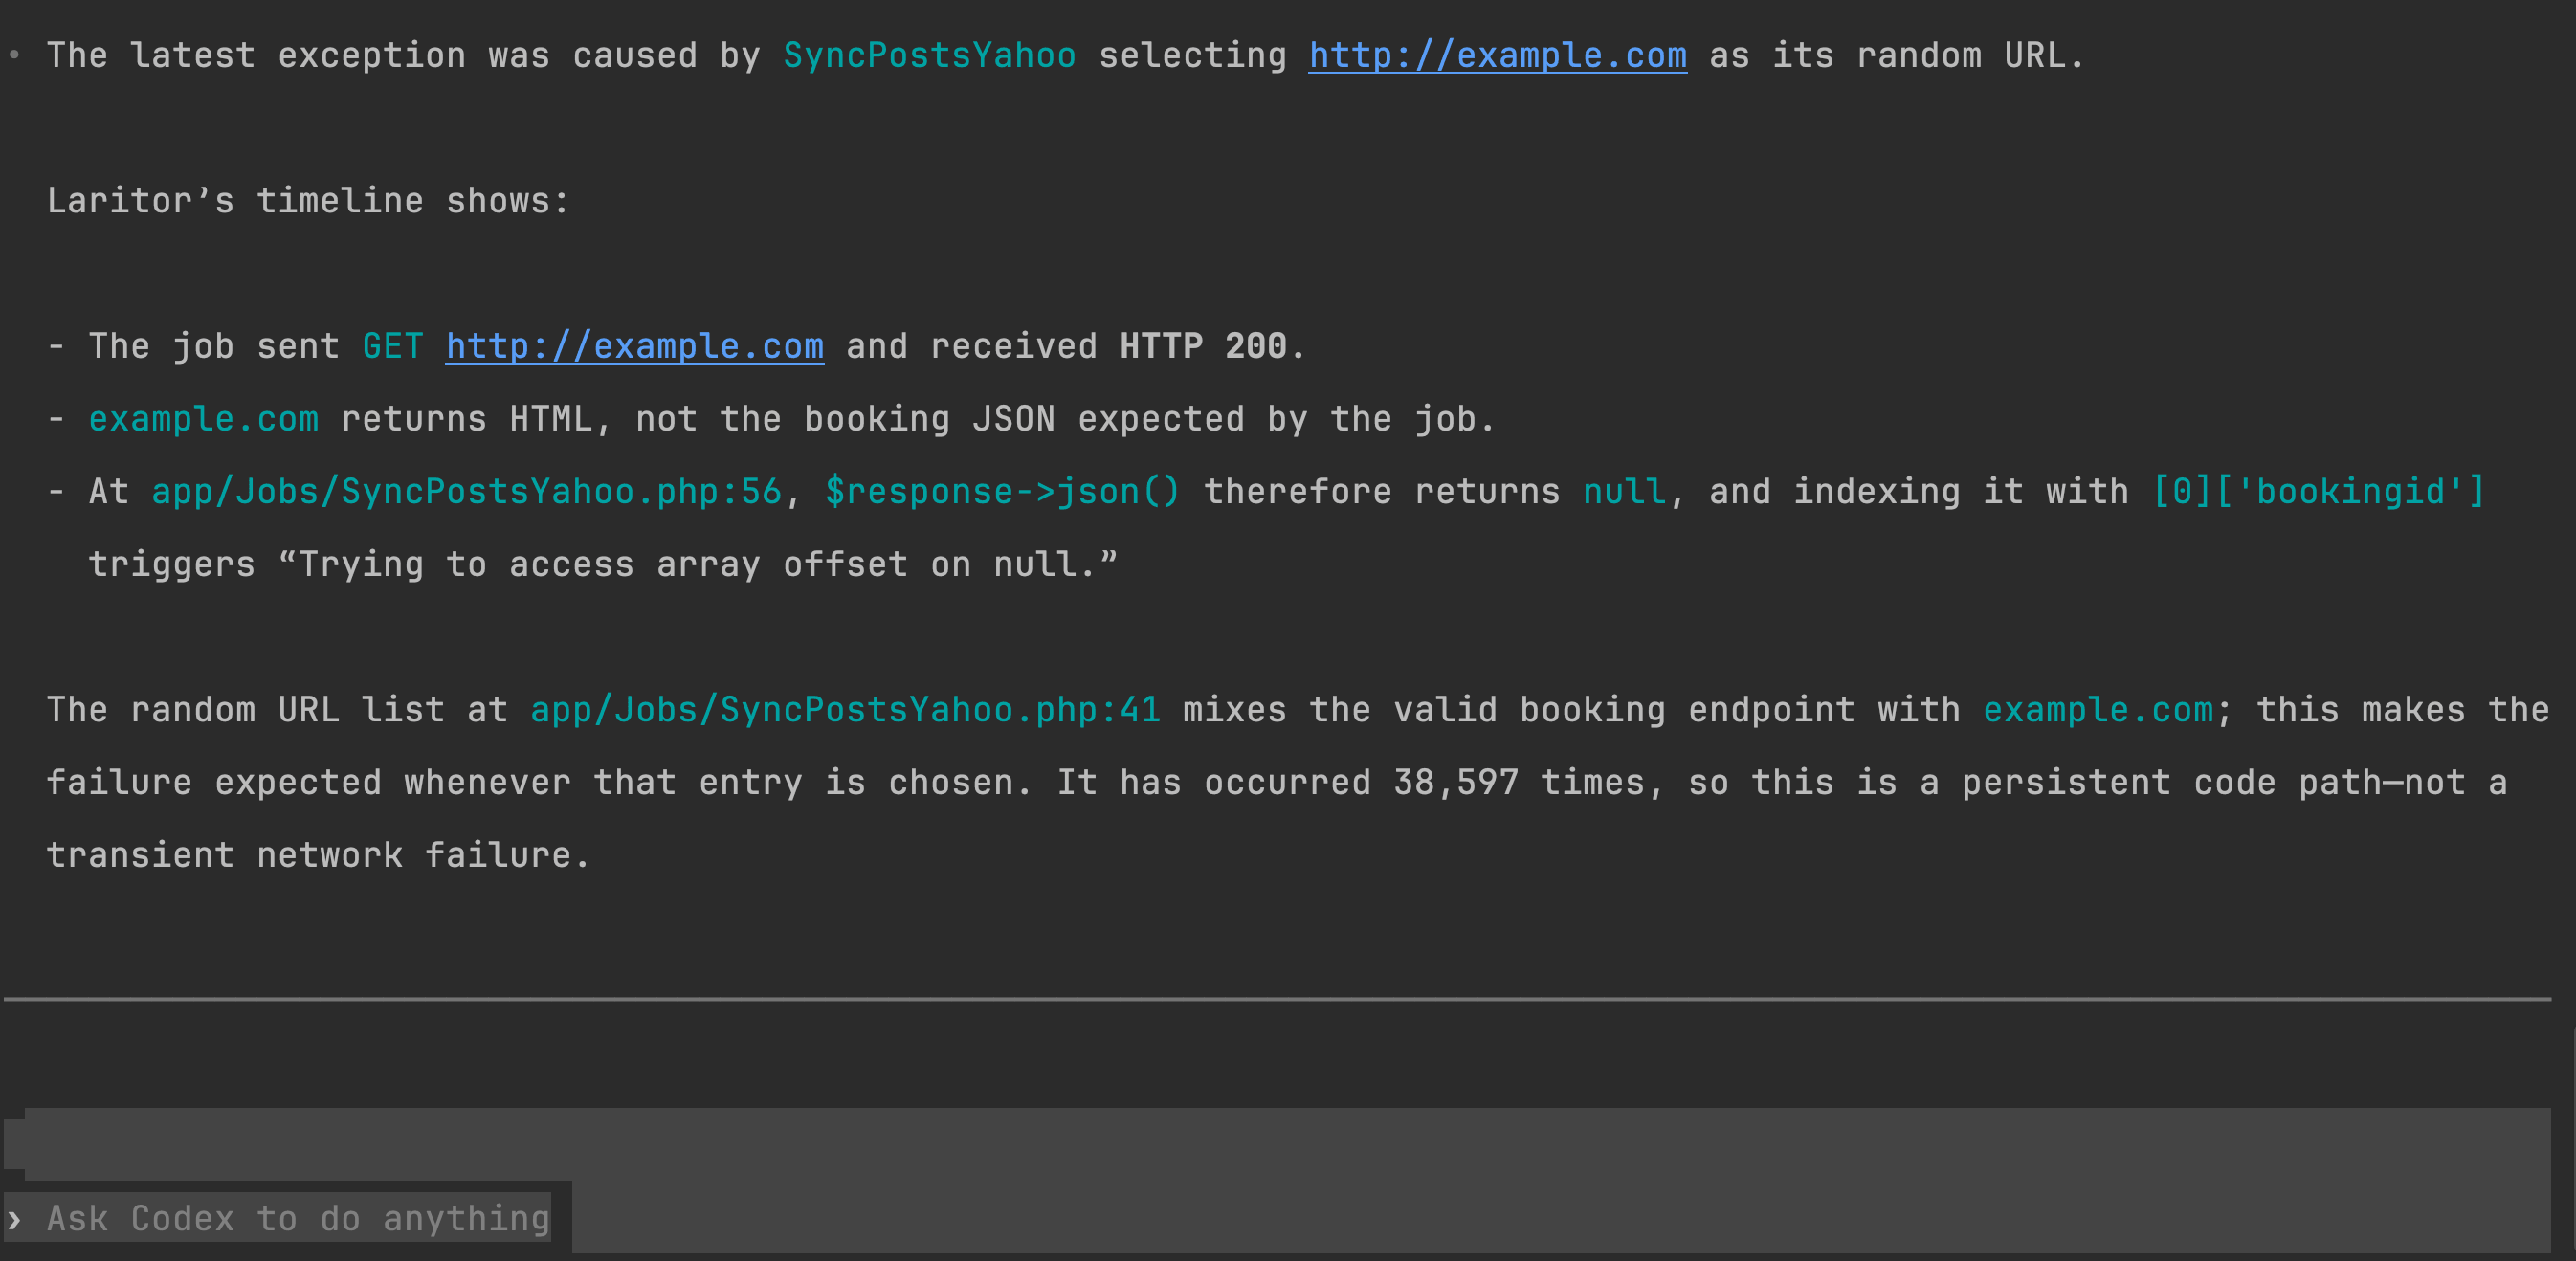
Start with problems, then add the performance views your team needs.
Request performance
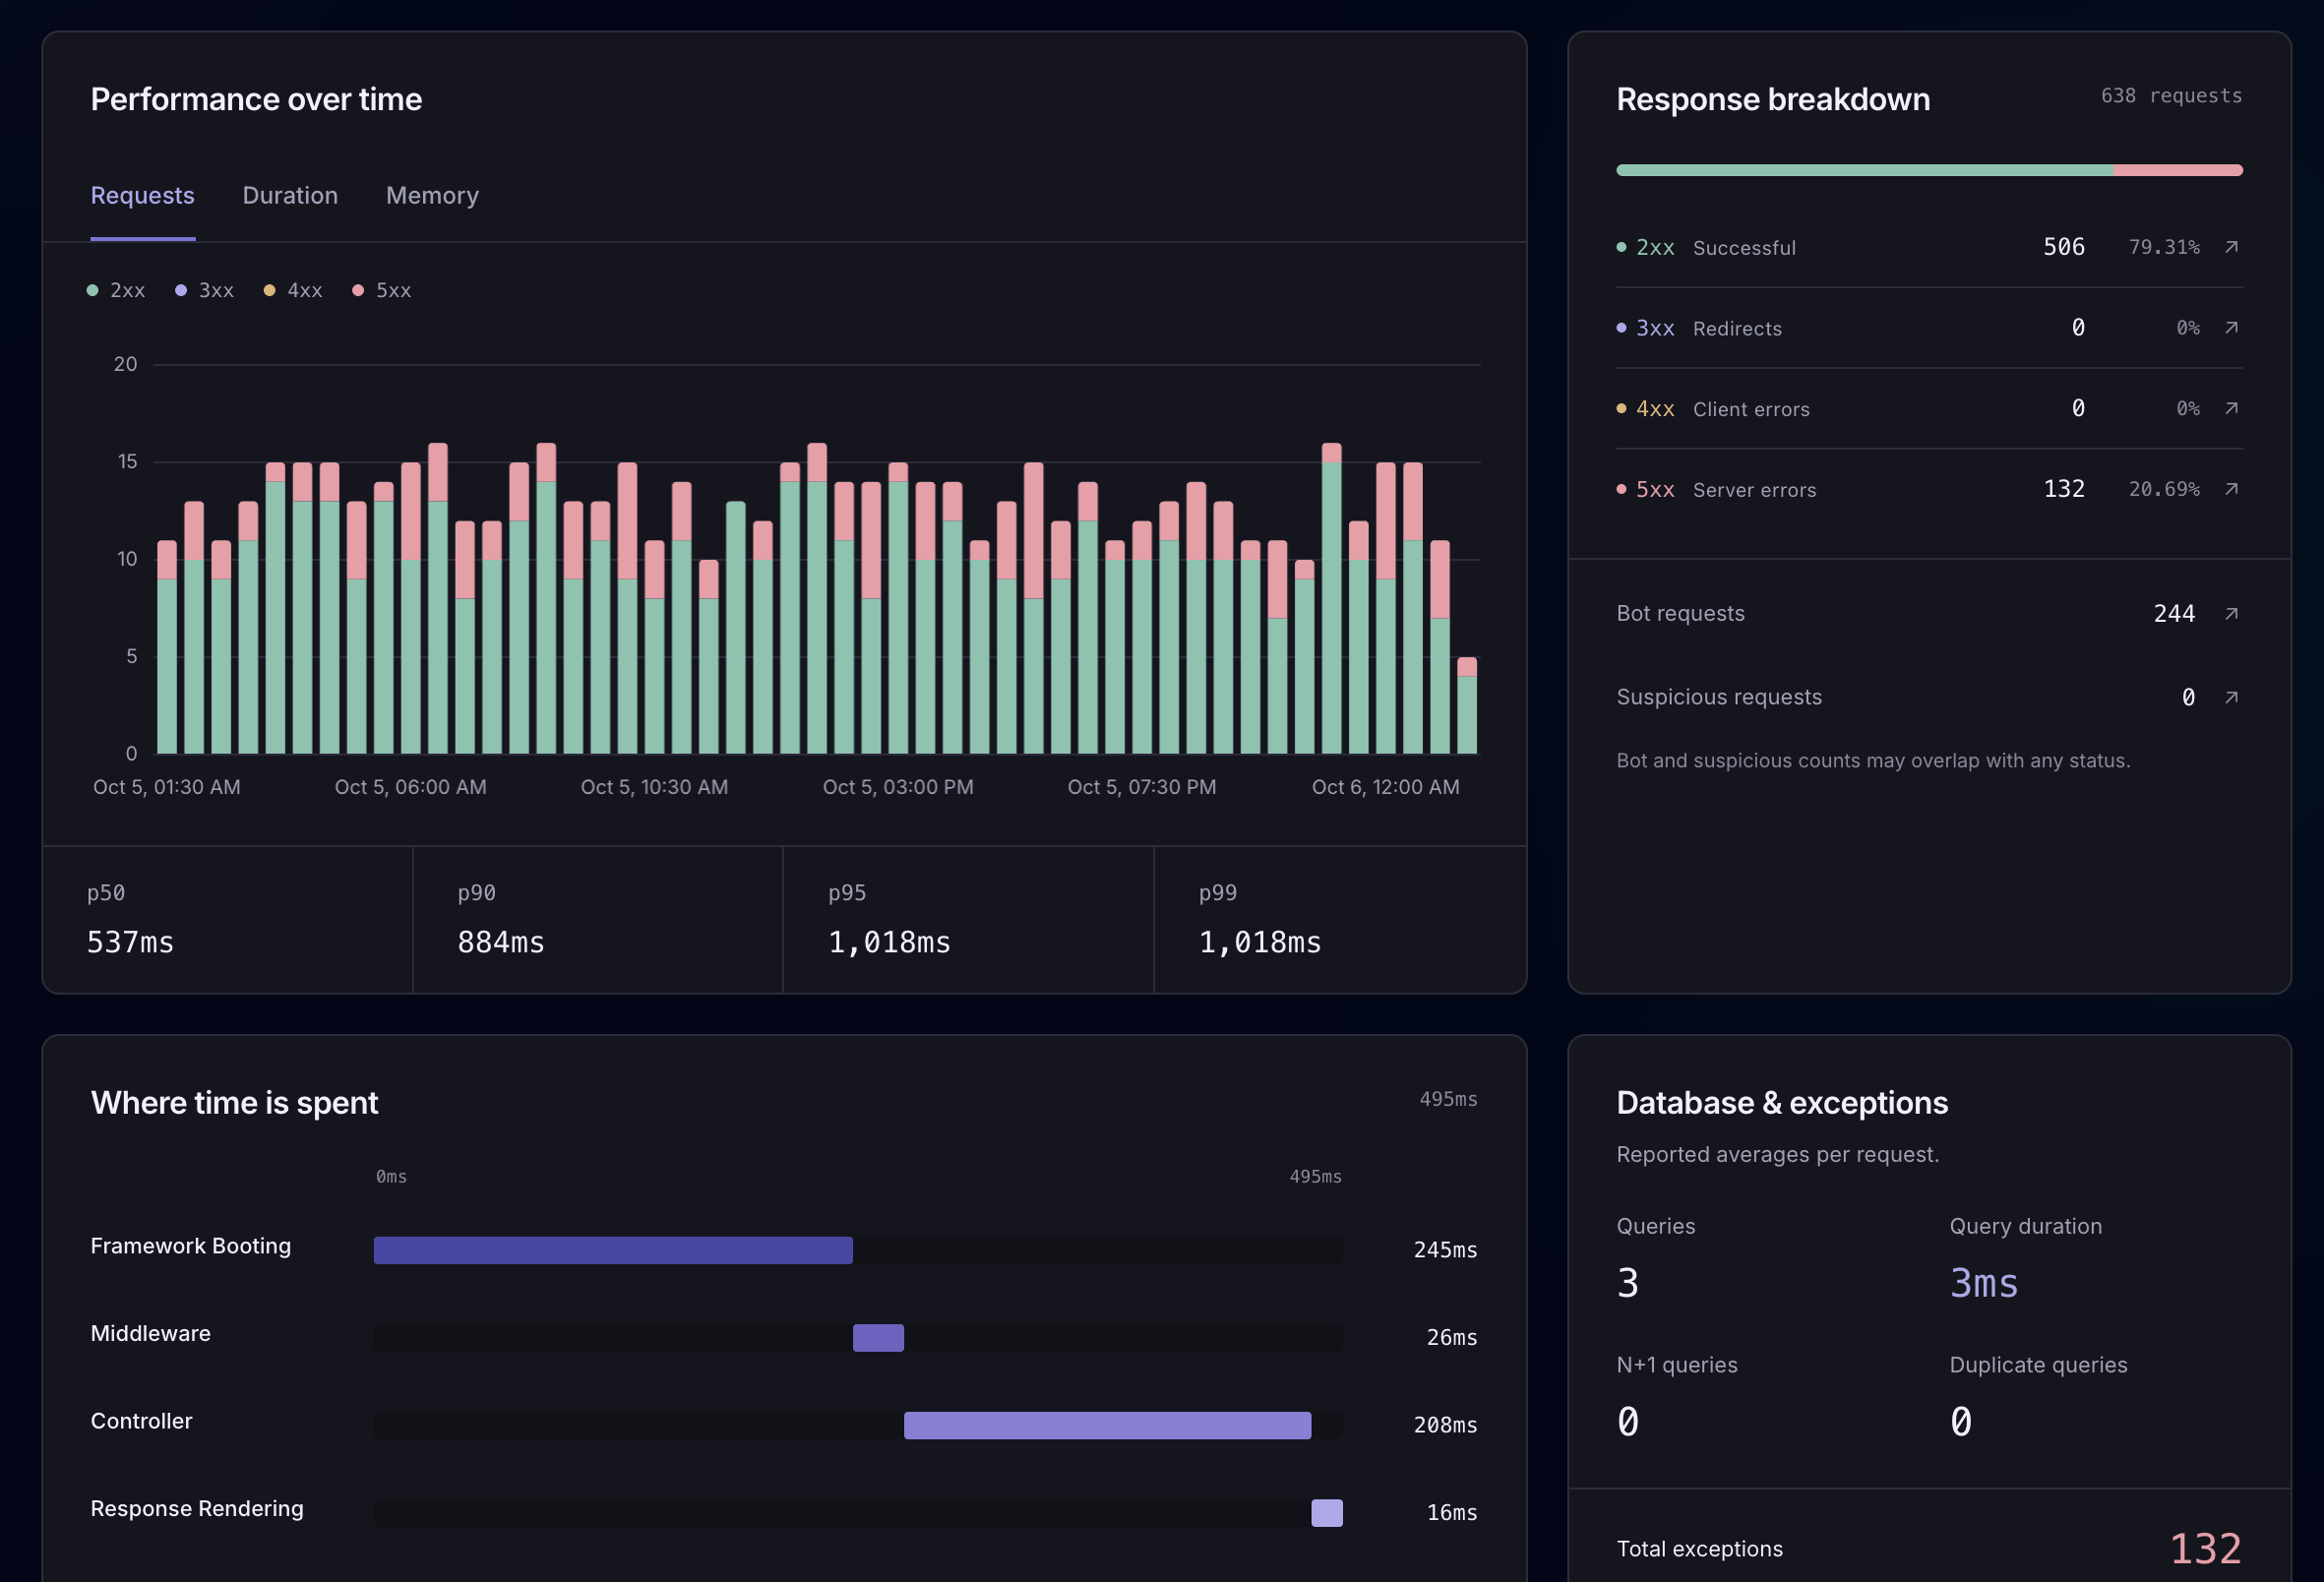
Review response times, percentiles, status codes, query time, and bot traffic. Open a retained request to inspect the events responsible for a slow or failing response.
Queuewatch focuses on queues, failures, and workers. Laritor brings request performance and queue investigation into the same application view.
Customizable dashboards
Arrange 85+ widgets for exceptions, requests, queries, queues, users, and server resources. Build unlimited dashboards around your application and the metrics your team follows.
Queuewatch offers failure analytics and worker monitoring. An equivalent general Laravel widget dashboard builder is not listed in its documentation.
Sessions and custom events
Inspect recorded requests across a session. Add custom events for checkout, order processing, or other business milestones to understand what the user tried to do.
Queuewatch records project, environment, job, and failure context. Laritor adds user session journeys and dedicated custom event resources for understanding the wider workflow.
Feature flag insights
Track Laravel Pennant evaluations, activation rates, execution durations, and related errors. Compare feature behavior with recorded application activity.
Automatic Pennant analytics are not listed in Queuewatch’s queue-focused integration. Laritor provides a dedicated view for feature usage and performance.
Performance in context
Review request volume, status codes, duration percentiles, and where time is spent. Open a retained request to inspect its queries, logs, API calls, and other recorded events. Explore request monitoring
Give teammates the view they need without another queue-only subscription.
Scheduled PDF reports
Choose performance metrics and get PDF snapshots by email. Keep tabs on your application without opening a dashboard, or share a report with your teammates.
Queuewatch provides failure and resolution analytics. Custom scheduled PDF reports for broader application performance are not listed.
Evaluate Laritor in your app
Use a representative app or environment to compare the details you receive, recording volume, and debugging workflow.
Create a Laritor account, install the Composer package, add your ingest endpoint and key, and run the sync command.
composer require binarybuilds/laritor-clientStart with exception tracker, issue tracker, or full observability. Register the generated filter, then review the data and privacy settings for your app.
Configure recording filtersInspect a known failed job or slow execution, test alert delivery, and compare measured overhead and billable event usage. If you run both tools, include their combined collection work in your evaluation.
Explore exception investigationCreate your dashboards, choose alert channels, schedule reports, and connect AI. Keep access to your existing Queuewatch reports while Laritor builds a new record. You can continue using Queuewatch’s remote retry and worker workflow during the evaluation. There is no documented automatic history import.
Explore Laritor guidesQuestions before switching
Laritor tracks exceptions, detects issues, and monitors Laravel performance. It helps you investigate failed jobs with their related queries, API calls, logs, and other recorded events. It also covers requests, commands, scheduled tasks, user sessions, server resources, feature flags, dashboards, in-app AI, and MCP.
Queuewatch focuses on Laravel queue failures, notifications, remote retries, failure resolution, and optional worker monitoring. Laritor provides broader exception tracking and application performance monitoring with related execution timelines. Choose Laritor when you want to understand both the failed job and the rest of your application; choose Queuewatch when its queue-specific recovery workflow is your main requirement.
Yes. Both are designed primarily for Laravel and have Composer packages that use Laravel concepts and events. Queuewatch also documents manual failure reporting through a REST API for other applications. Laravel native describes the primary product focus; it does not mean every tool with a Laravel integration has the same application coverage.
Yes. When your recording configuration retains the execution, Laritor includes its related recorded queries, outbound requests, logs, cache activity, and custom events. Inspect that timeline alongside the exception and job details. Events you disable, filter out, or do not instrument will not be available.
Yes. The released v1.3.1 package includes opt-in worker starts, heartbeats, memory, and stops on Laravel 12.20 or newer. It requires a running scheduler and shared persistent cache. Stop reason fields depend on the Laravel version. This is distinct from Laritor’s job execution, dispatch delay, queue wait, and throughput investigation.
Yes, on Pro and above after you enable the retry endpoint and configure its callback URL. The released client signs requests using the project API key, and only failures captured with retry enabled contain the serialized command needed to reconstruct the job. Laritor’s documentation does not list an equivalent dashboard-triggered retry endpoint; use your Laravel retry workflow after investigation.
It uses one failed-job occurrence count for both tools. One retained JobFailed occurrence is assumed to create one Queuewatch report. For Laritor, that count is multiplied by the average billable events recorded per failed job, including related activity and 2 KB increments. It estimates only the shared failed-job workload; recording requests, successful jobs, or other activity adds Laritor events.
No. It selects the smallest paid report allowance, starting with Pro for up to 1,000 failed-job reports, Team for up to 10,000, and Business above that. Extra project or team member requirements can require a higher tier even at a lower failure count. Trials and recurring free allowances are excluded.
Its public pricing shows $16, $48, and $160 per month with yearly billing and a 20% annual discount, alongside reference prices. The calculator uses those published annual monthly equivalents rather than inferring a monthly subscription rate. Laritor is shown at its published monthly rate. Confirm the billing term and current checkout price before subscribing.
The calculator shows “Ask for a quote” when the estimate is above $500 per month. Exactly $500 remains numeric. Queuewatch’s published Business allowance is unlimited failed-job reports; this does not imply unlimited API request rate, worker entitlement, or every enterprise option. Those details must be confirmed with Queuewatch.
Yes. Laritor offers in-app AI recommendations with configurable providers and a hosted read-only MCP server for exception details and recorded execution context. Your coding agent can inspect that context alongside your code to investigate a fix. Queuewatch documents REST integration and retries; an equivalent in-app AI assistant or MCP server was not found in the reviewed public documentation.
Yes. Exceptions-only retains configured events for executions with an exception. Issues-only retains configured events when an issue is detected, such as a failed job or slow request. Full observability retains all configured activity. Queuewatch reports failures through JobFailed and optionally worker lifecycle events; these products use different recording boundaries.
Laritor provides collection settings and client-side redaction before ingestion. Queuewatch’s released client can disable job payload collection and filters jobs, queues, and exception classes. Its older advanced configuration guide describes field scrubbing, but those settings are not present in the reviewed released configuration. Check the installed version, exception messages, and serialized retry data rather than assuming every sensitive field is masked.
Yes. Queuewatch explicitly supports Horizon, and Laritor can monitor Laravel job activity in an app that uses Horizon. Keep Horizon for running and managing your Redis workers. Queuewatch’s optional worker heartbeats still need a separate running Laravel scheduler and persistent shared cache; Horizon does not run the scheduler for you.
Yes. Install and configure Laritor alongside Queuewatch in a representative environment. Compare failure details, related events, alerts, billable usage, and combined collection overhead. You can keep Queuewatch for remote retries and worker lifecycle monitoring while evaluating Laritor’s broader application views.
Laritor starts recording new activity after installation and configuration. There is no documented automatic import of Queuewatch failure history. Keep access to your existing reports while Laritor builds a new record of your application.
About this comparison
Published by Laritor, independently of Queuewatch. Official product pages, failure and resolution analytics, REST and retry documentation, the released v1.3.1 Laravel package, and its configuration, failure listener, worker monitoring, and CLI were reviewed on . Queuewatch’s newer worker monitoring is included. Its released listener transmits up to 20 trace frames and does not collect the related SQL, HTTP, or log timeline of the failing job.
“Not listed” is a documentation finding. Custom integration may meet a need beyond the listed product resources. Older Queuewatch guides differ from the released package on payload scrubbing, retry authentication, and version support; the reviewed release takes precedence for implementation claims. The public API rate-limit guide also lists different plan allowances from the homepage. The calculator uses the homepage’s report quotas and published annual monthly equivalents, with a clear annual billing label. It does not infer monthly rates or worker entitlement. The shared workload is failed jobs only; broader Laritor recording adds events. Prices exclude tax, trials, free allowances, custom contracts, and optional enterprise hosting. More projects or members may require a higher Queuewatch tier. Confirm current limits and checkout terms before subscribing.
Start with the data you need
Track exceptions, detect issues, and monitor performance.
Try Laritor with 300K events free.